Show PDB file:   
         Plain Text   HTML   (compressed file size)
QuickSearch:   
by PDB,NDB,UniProt,PROSITE Code or Search Term(s)  
(-)Asymmetric Unit
(-)Asym. Unit - sites
(-)Biological Unit 1
(-)Biol. Unit 1 - sites
(-)Biological Unit 2
(-)Biological Unit 3
collapse expand < >
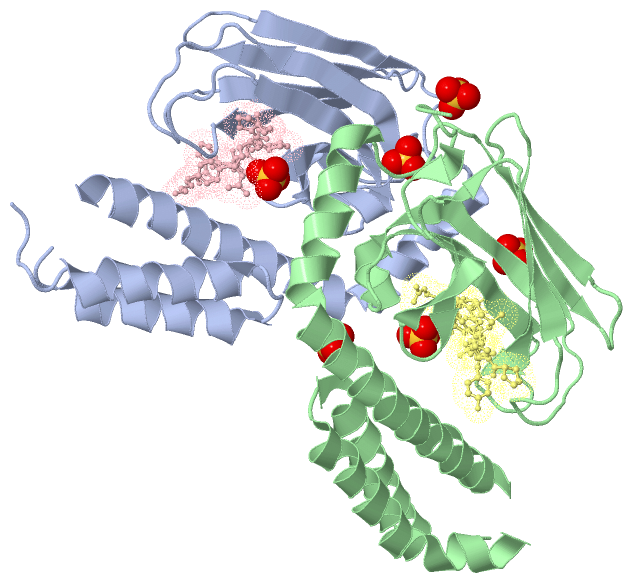
Image Asymmetric Unit
Asymmetric Unit  (Jmol Viewer)
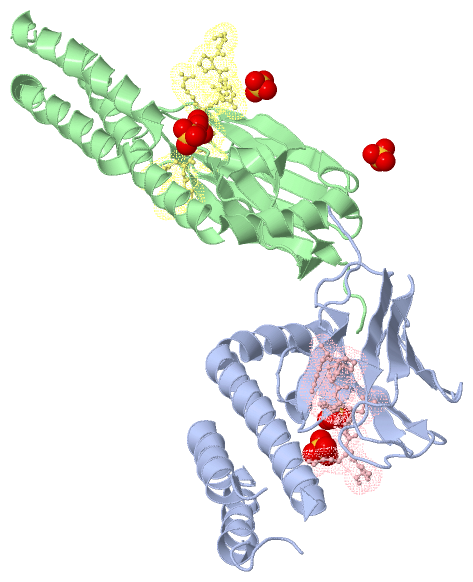
Image Asym. Unit - sites
Asym. Unit - sites  (Jmol Viewer)
Image Biological Unit 1
Biological Unit 1  (Jmol Viewer)
Image Biol. Unit 1 - sites
Biol. Unit 1 - sites  (Jmol Viewer)
Image Biological Unit 2
Biological Unit 2  (Jmol Viewer)
Image Biological Unit 3
Biological Unit 3  (Jmol Viewer)

(-) Description

Title :  CRYSTAL STRUCTURE OF THE SUBSTRATE BINDING DOMAIN OF E.COLI DNAK IN COMPLEX WITH THE ANTIMICROBIAL PEPTIDE ONCOCIN
 
Authors :  M. Zahn, N. Straeter
Date :  08 Feb 11  (Deposition) - 23 Mar 11  (Release) - 11 May 11  (Revision)
Method :  X-RAY DIFFRACTION
Resolution :  2.28
Chains :  Asym. Unit :  A,B,C,D
Biol. Unit 1:  A,C  (1x)
Biol. Unit 2:  B,D  (1x)
Biol. Unit 3:  A (1x),B (1x),C (1x),D (1x)
Keywords :  Peptide/Protein Binding, Chaperone-Antimicrobial Protein Complex (Keyword Search: [Gene Ontology, PubMed, Web (Google)] )
 
Reference :  D. Knappe, M. Zahn, U. Sauer, G. Schiffer, N. Strater, R. Hoffmann
Rational Design Of Oncocin Derivatives With Superior Protease Stabilities And Antibacterial Activities Based On The High-Resolution Structure Of The Oncocin-Dnak Complex.
Chembiochem V. 12 874 2011
PubMed-ID: 21387510  |  Reference-DOI: 10.1002/CBIC.201000792

(-) Compounds

Molecule 1 - CHAPERONE PROTEIN DNAK
    Chains: A, B
    Engineered: YES
    Expression System: ESCHERICHIA COLI
    Expression System Plasmid: PET15B
    Expression System Strain: ROSETTA(DE3)PLYSS
    Expression System Taxid: 562
    Expression System Vector Type: PLASMID
    Fragment: UNP RESIDUES 389-607
    Gene: DNAK, GROP, GRPF, SEG
    Organism Scientific: ESCHERICHIA COLI
    Organism Taxid: 83333
    Strain: K12
    Synonym: HSP70, HEAT SHOCK 70 KDA PROTEIN, HEAT SHOCK PROTEIN 70
 
Molecule 2 - ANTIMICROBIAL PEPTIDE ONCOCIN
    Chains: C, D
    Engineered: YES
    Organism Scientific: ONCOPELTUS FASCIATUS
    Organism Taxid: 7536
    Other Details: THIS SEQUENCE IS DERIVED FROM ONCOPELTUS FASCIATUS AND OPTIMIZED FOR THE TREATMENT OF GRAM-NEGATIVE PATHOGENS
    Synthetic: YES

 Structural Features

(-) Chains, Units

  1234
Asymmetric Unit : ABCD
Biological Unit 1 (1x): A C 
Biological Unit 2 (1x):  B D
Biological Unit 3 (1x): A (1x)B (1x)C (1x)D (1x)

Summary Information (see also Sequences/Alignments below)

(-) Ligands, Modified Residues, Ions  (1, 6)

Asymmetric Unit (1, 6)
No.NameCountTypeFull Name
1SO46Ligand/IonSULFATE ION
Biological Unit 1 (1, 2)
No.NameCountTypeFull Name
1SO42Ligand/IonSULFATE ION
Biological Unit 2 (1, 4)
No.NameCountTypeFull Name
1SO44Ligand/IonSULFATE ION
Biological Unit 3 (1, 4)
No.NameCountTypeFull Name
1SO44Ligand/IonSULFATE ION

(-) Sites  (6, 6)

Asymmetric Unit (6, 6)
No.NameEvidenceResiduesDescription
1AC1SOFTWAREHOH A:153 , HOH A:165 , LYS A:452 , SER A:453 , LYS B:452BINDING SITE FOR RESIDUE SO4 A 1
2AC2SOFTWAREHOH B:152 , LYS B:502 , SER B:504BINDING SITE FOR RESIDUE SO4 B 2
3AC3SOFTWAREARG B:447 , ARG B:536 , LYS B:577 , GLU B:579BINDING SITE FOR RESIDUE SO4 B 4
4AC4SOFTWAREGLU B:402 , GLY B:405 , GLY B:406 , PRO D:8BINDING SITE FOR RESIDUE SO4 B 5
5AC5SOFTWAREASP A:510 , HOH B:120 , ASN B:458BINDING SITE FOR RESIDUE SO4 B 6
6AC6SOFTWAREHOH A:119 , MET A:404 , GLY A:405 , ARG C:9BINDING SITE FOR RESIDUE SO4 C 20

(-) SS Bonds  (0, 0)

(no "SS Bond" information available for 3QNJ)

(-) Cis Peptide Bonds  (2, 2)

Asymmetric Unit
No.Residues
1Ile A:418 -Pro A:419
2Ile B:418 -Pro B:419

 Sequence-Structure Mapping

(-) SAPs(SNPs)/Variants  (0, 0)

(no "SAP(SNP)/Variant" information available for 3QNJ)

(-) PROSITE Motifs  (0, 0)

(no "PROSITE Motif" information available for 3QNJ)

(-) Exons   (0, 0)

(no "Exon" information available for 3QNJ)

(-) Sequences/Alignments

Asymmetric Unit
   Reformat: Number of residues per line =  ('0' or empty: single-line sequence representation)
  Number of residues per labelling interval =   
  UniProt sequence: complete  aligned part    
   Show mapping: SCOP domains CATH domains Pfam domains Secondary structure (by author)
SAPs(SNPs) PROSITE motifs Exons
(details for a mapped element are shown in a popup box when the mouse pointer rests over it)
Chain A from PDB  Type:PROTEIN  Length:204
 aligned with DNAK_ECOLI | P0A6Y8 from UniProtKB/Swiss-Prot  Length:638

    Alignment length:210
                                   398       408       418       428       438       448       458       468       478       488       498       508       518       528       538       548       558       568       578       588       598
           DNAK_ECOLI   389 VLLLDVTPLSLGIETMGGVMTTLIAKNTTIPTKHSQVFSTAEDNQSAVTIHVLQGERKRAADNKSLGQFNLDGINPAPRGMPQIEVTFDIDADGILHVSAKDKNSGKEQKITIKASSGLNEDEIQKMVRDAEANAEADRKFEELVQTRNQGDHLLHSTRKQVEEAGDKLPADDKTAIESALTALETALKGEDKAAIEAKMQELAQVSQKL 598
               SCOP domains ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ SCOP domains
               CATH domains ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ CATH domains
               Pfam domains ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ Pfam domains
         Sec.struct. author ..........eeeee...eeeeee.......eeeeeee.........eeeeeee....hhhhheeeeeeee............eeeeeee.....eeeeeee.....eeeeee......hhhhhhhhhhhhhhhhhhhhhhhhhhhhhhhhhhhhhhhhhh.------.....hhhhhhhhhhhhhhh...hhhhhhhhhhhhhhhh... Sec.struct. author
                 SAPs(SNPs) ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ SAPs(SNPs)
                    PROSITE ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ PROSITE
                 Transcript ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ Transcript
                 3qnj A 389 VLLLDVTPLSLGIETMGGVMTTLIAKNTTIPTKHSQVFSTAEDNQSAVTIHVLQGERKRAADNKSLGQFNLDGINPAPRGMPQIEVTFDIDADGILHVSAKDKNSGKEQKITIKASSGLNEDEIQKMVRDAEANAEADRKFEELVQTRNQGDHLLHSTRKQV------LPADDKTAIESALTALETALKGEDKAAIEAKMQELAQVSQKL 598
                                   398       408       418       428       438       448       458       468       478       488       498       508       518       528       538       548 |     558       568       578       588       598
                                                                                                                                                                                           550    557                                         

Chain B from PDB  Type:PROTEIN  Length:211
 aligned with DNAK_ECOLI | P0A6Y8 from UniProtKB/Swiss-Prot  Length:638

    Alignment length:214
                                   398       408       418       428       438       448       458       468       478       488       498       508       518       528       538       548       558       568       578       588       598    
           DNAK_ECOLI   389 VLLLDVTPLSLGIETMGGVMTTLIAKNTTIPTKHSQVFSTAEDNQSAVTIHVLQGERKRAADNKSLGQFNLDGINPAPRGMPQIEVTFDIDADGILHVSAKDKNSGKEQKITIKASSGLNEDEIQKMVRDAEANAEADRKFEELVQTRNQGDHLLHSTRKQVEEAGDKLPADDKTAIESALTALETALKGEDKAAIEAKMQELAQVSQKLMEIA 602
               SCOP domains ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- SCOP domains
               CATH domains ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- CATH domains
           Pfam domains (1) HSP70-3qnjB01 B:389-602                                                                                                                                                                                                Pfam domains (1)
           Pfam domains (2) HSP70-3qnjB02 B:389-602                                                                                                                                                                                                Pfam domains (2)
         Sec.struct. author .....ee...eeeee...eeeeee...ee..eeeeeeeee......eeeeeeee....hhhhheeeeeeeee...........eeeeeee.....eeeeeee.....eeeeee......hhhhhhhhhhhhhhhhhhhhhhhhhhhhhhhhhhhhhhhhhhhhh---..hhhhhhhhhhhhhhhhhhhhh.hhhhhhhhhhhhhhhhhhhhhhh Sec.struct. author
                 SAPs(SNPs) ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- SAPs(SNPs)
                    PROSITE ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- PROSITE
                 Transcript ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- Transcript
                 3qnj B 389 VLLLDVTPLSLGIETMGGVMTTLIAKNTTIPTKHSQVFSTAEDNQSAVTIHVLQGERKRAADNKSLGQFNLDGINPAPRGMPQIEVTFDIDADGILHVSAKDKNSGKEQKITIKASSGLNEDEIQKMVRDAEANAEADRKFEELVQTRNQGDHLLHSTRKQVEE---KLPADDKTAIESALTALETALKGEDKAAIEAKMQELAQVSQKLMEIA 602
                                   398       408       418       428       438       448       458       468       478       488       498       508       518       528       538       548   |   558       568       578       588       598    
                                                                                                                                                                                             552 556                                              

Chain C from PDB  Type:PROTEIN  Length:8
                                        
               SCOP domains -------- SCOP domains
               CATH domains -------- CATH domains
               Pfam domains -------- Pfam domains
         Sec.struct. author ........ Sec.struct. author
                 SAPs(SNPs) -------- SAPs(SNPs)
                    PROSITE -------- PROSITE
                 Transcript -------- Transcript
                 3qnj C   3 KPPYLPRP  10

Chain D from PDB  Type:PROTEIN  Length:10
                                          
               SCOP domains ---------- SCOP domains
               CATH domains ---------- CATH domains
               Pfam domains ---------- Pfam domains
         Sec.struct. author ..ee...... Sec.struct. author
                 SAPs(SNPs) ---------- SAPs(SNPs)
                    PROSITE ---------- PROSITE
                 Transcript ---------- Transcript
                 3qnj D   4 PPYLPRPRPP  13
                                    13

   Legend:   → Mismatch (orange background)
  - → Gap (green background, '-', border residues have a numbering label)
    → Modified Residue (blue background, lower-case, 'x' indicates undefined single-letter code, labelled with number + name)
  x → Chemical Group (purple background, 'x', labelled with number + name, e.g. ACE or NH2)
  extra numbering lines below/above indicate numbering irregularities and modified residue names etc., number ends below/above '|'

 Classification and Annotation

(-) SCOP Domains  (0, 0)

(no "SCOP Domain" information available for 3QNJ)

(-) CATH Domains  (0, 0)

(no "CATH Domain" information available for 3QNJ)

(-) Pfam Domains  (1, 2)

Asymmetric Unit

(-) Gene Ontology  (21, 21)

Asymmetric Unit(hide GO term definitions)
Chain A,B   (DNAK_ECOLI | P0A6Y8)
molecular function
    GO:0043531    ADP binding    Interacting selectively and non-covalently with ADP, adenosine 5'-diphosphate.
    GO:0005524    ATP binding    Interacting selectively and non-covalently with ATP, adenosine 5'-triphosphate, a universally important coenzyme and enzyme regulator.
    GO:0000166    nucleotide binding    Interacting selectively and non-covalently with a nucleotide, any compound consisting of a nucleoside that is esterified with (ortho)phosphate or an oligophosphate at any hydroxyl group on the ribose or deoxyribose.
    GO:0005515    protein binding    Interacting selectively and non-covalently with any protein or protein complex (a complex of two or more proteins that may include other nonprotein molecules).
    GO:0044183    protein binding involved in protein folding    Interacting selectively and non-covalently with any protein or protein complex (a complex of two or more proteins that may include other nonprotein molecules) that contributes to the process of protein folding.
    GO:0016989    sigma factor antagonist activity    The function of binding to a sigma factor and stopping, preventing or reducing the rate of its transcriptional activity.
    GO:0051082    unfolded protein binding    Interacting selectively and non-covalently with an unfolded protein.
    GO:0008270    zinc ion binding    Interacting selectively and non-covalently with zinc (Zn) ions.
biological process
    GO:0006260    DNA replication    The cellular metabolic process in which a cell duplicates one or more molecules of DNA. DNA replication begins when specific sequences, known as origins of replication, are recognized and bound by initiation proteins, and ends when the original DNA molecule has been completely duplicated and the copies topologically separated. The unit of replication usually corresponds to the genome of the cell, an organelle, or a virus. The template for replication can either be an existing DNA molecule or RNA.
    GO:0034620    cellular response to unfolded protein    Any process that results in a change in state or activity of a cell (in terms of movement, secretion, enzyme production, gene expression, etc.) as a result of an unfolded protein stimulus.
    GO:0070389    chaperone cofactor-dependent protein refolding    The process of assisting in the restoration of the biological activity of an unfolded or misfolded protein, which is dependent on additional protein cofactors. This process occurs over one or several cycles of nucleotide hydrolysis-dependent binding and release.
    GO:0051085    chaperone mediated protein folding requiring cofactor    The process of assisting in the correct posttranslational noncovalent assembly of proteins, which is dependent on additional protein cofactors. This process occurs over one or several cycles of nucleotide hydrolysis-dependent binding and release.
    GO:0006461    protein complex assembly    The aggregation, arrangement and bonding together of a set of components to form a protein complex.
    GO:0043241    protein complex disassembly    The disaggregation of a protein complex into its constituent components. Protein complexes may have other associated non-protein prosthetic groups, such as nucleic acids, metal ions or carbohydrate groups.
    GO:0006457    protein folding    The process of assisting in the covalent and noncovalent assembly of single chain polypeptides or multisubunit complexes into the correct tertiary structure.
    GO:1903506    regulation of nucleic acid-templated transcription    Any process that modulates the frequency, rate or extent of nucleic acid-templated transcription.
    GO:0009408    response to heat    Any process that results in a change in state or activity of a cell or an organism (in terms of movement, secretion, enzyme production, gene expression, etc.) as a result of a heat stimulus, a temperature stimulus above the optimal temperature for that organism.
cellular component
    GO:0005737    cytoplasm    All of the contents of a cell excluding the plasma membrane and nucleus, but including other subcellular structures.
    GO:0005829    cytosol    The part of the cytoplasm that does not contain organelles but which does contain other particulate matter, such as protein complexes.
    GO:0016020    membrane    A lipid bilayer along with all the proteins and protein complexes embedded in it an attached to it.
    GO:0005886    plasma membrane    The membrane surrounding a cell that separates the cell from its external environment. It consists of a phospholipid bilayer and associated proteins.

 Visualization

(-) Interactive Views

Asymmetric Unit
  Complete Structure
    Jena3D(integrated viewing of ligand, site, SAP, PROSITE, SCOP information)
    WebMol | AstexViewer[tm]@PDBe
(Java Applets, require no local installation except for Java; loading may be slow)
    STRAP
(Java WebStart application, automatic local installation, requires Java; full application with system access!)
    RasMol
(require local installation)
    Molscript (VRML)
(requires installation of a VRML viewer; select preferred view via VRML and generate a mono or stereo PDF format file)
 
  Ligands, Modified Residues, Ions
    SO4  [ RasMol | Jena3D ]  +environment [ RasMol | Jena3D ]
 
  Sites
    AC1  [ RasMol ]  +environment [ RasMol ]
    AC2  [ RasMol ]  +environment [ RasMol ]
    AC3  [ RasMol ]  +environment [ RasMol ]
    AC4  [ RasMol ]  +environment [ RasMol ]
    AC5  [ RasMol ]  +environment [ RasMol ]
    AC6  [ RasMol ]  +environment [ RasMol ]
 
  Cis Peptide Bonds
    Ile A:418 - Pro A:419   [ RasMol ]  
    Ile B:418 - Pro B:419   [ RasMol ]  
 
Biological Units
  Complete Structure
    Biological Unit 1  [ Jena3D ]
    Biological Unit 2  [ Jena3D ]
    Biological Unit 3  [ Jena3D ]

(-) Still Images

Jmol
  protein: cartoon or spacefill or dots and stick; nucleic acid: cartoon and stick; ligands: spacefill; active site: stick
Molscript
  protein, nucleic acid: cartoon; ligands: spacefill; active site: ball and stick

 Databases and Analysis Tools

(-) Databases

Access by PDB/NDB ID
  3qnj
    Family and Domain Information: ProDom | SYSTERS
    General Structural Information: GlycoscienceDB | MMDB | NDB | OCA | PDB | PDBe | PDBj | PDBsum | PDBWiki | PQS | PROTEOPEDIA
    Orientation in Membranes: OPM
    Protein Surface: SURFACE
    Secondary Structure: DSSP (structure derived) | HSSP (homology derived)
    Structural Genomics: GeneCensus
    Structural Neighbours: CE | VAST
    Structure Classification: CATH | Dali | SCOP
    Validation and Original Data: BMRB Data View | BMRB Restraints Grid | EDS | PROCHECK | RECOORD | WHAT_CHECK
 
Access by UniProt ID/Accession number
  DNAK_ECOLI | P0A6Y8
    Comparative Protein Structure Models: ModBase
    Genomic Information: Ensembl
    Protein-protein Interaction: DIP
    Sequence, Family and Domain Information: InterPro | Pfam | SMART | UniProtKB/SwissProt
 
Access by Enzyme Classificator   (EC Number)
  (no 'Enzyme Classificator' available)
    General Enzyme Information: BRENDA | EC-PDB | Enzyme | IntEnz
    Pathway: KEGG | MetaCyc
 
Access by Disease Identifier   (MIM ID)
  (no 'MIM ID' available)
    Disease Information: OMIM
 
Access by GenAge ID
  (no 'GenAge ID' available)
    Age Related Information: GenAge

(-) Analysis Tools

Access by PDB/NDB ID
    Domain Information: XDom
    Interatomic Contacts of Structural Units: CSU
    Ligand-protein Contacts: LPC
    Protein Cavities: castP
    Sequence and Secondary Structure: PDBCartoon
    Structure Alignment: STRAP(Java WebStart application, automatic local installation, requires Java; full application with system access!)
    Structure and Sequence Browser: STING
 
Access by UniProt ID/Accession number
  DNAK_ECOLI | P0A6Y8
    Protein Disorder Prediction: DisEMBL | FoldIndex | GLOBPLOT (for more information see DisProt)

 Related Entries

(-) Entries Sharing at Least One Protein Chain (UniProt ID)

UniProtKB/Swiss-Prot
        DNAK_ECOLI | P0A6Y8: 1bpr 1dg4 1dkg 1dkx 1dky 1dkz 1q5l 2bpr 2kho 3dpo 3dpp 3dpq 4b9q 4e81 4ezn 4ezo 4ezp 4ezq 4ezr 4ezs 4ezt 4ezu 4ezv 4ezw 4ezx 4ezy 4ezz 4f00 4f01 4hy9 4hyb 4jn4 4jne 4jnf 4jwc 4jwd 4jwe 4jwi 4r5g 4r5i 4r5j 4r5k 4r5l

(-) Related Entries Specified in the PDB File

1dkx 1dky 1dkz 3dpo 3dpp 3dpq